Frontdesk Agent
Overview
A multilingual messaging receptionist for a clinic and a shop: one Python engine with Instagram and WhatsApp adapters that answers from approved information, books appointments and hands over to staff, without ever inventing a price, a free time or medical advice.
Stack
Python, Pydantic AI, Gemini on Vertex AI (EU), Postgres with pgvector, Cloud Tasks, cal.com, Google Calendar, Instagram and WhatsApp APIs, Hypothesis
What I built
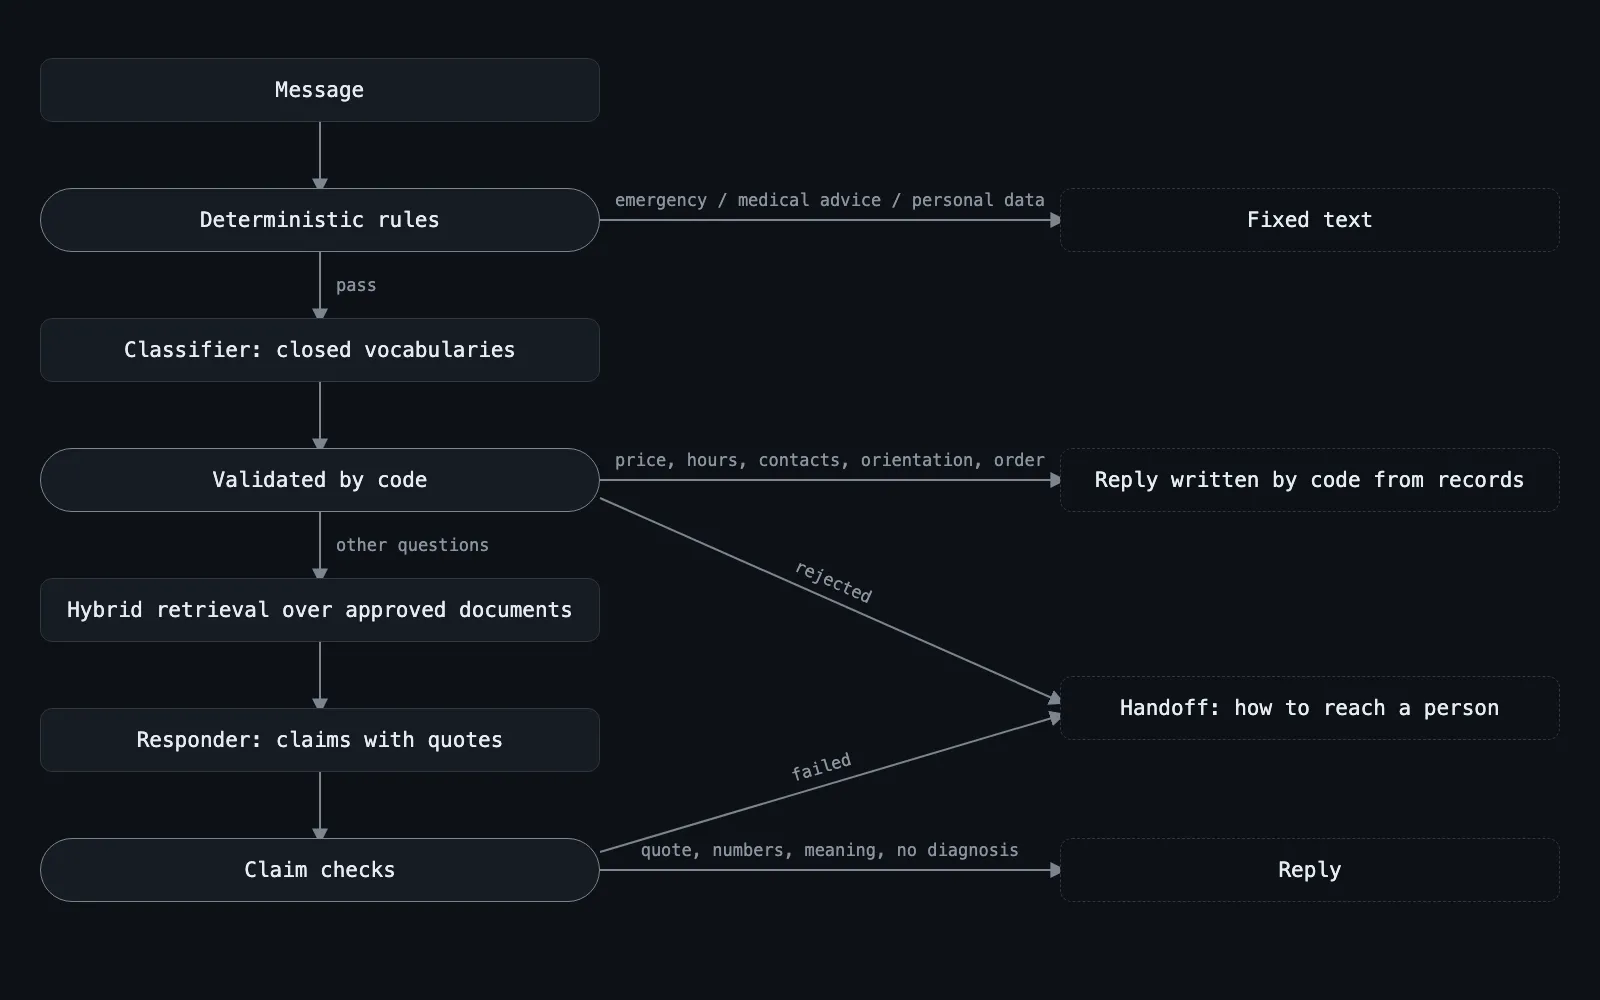
- Safety rules that run before any model call: emergencies, requests for medical advice and personal data get fixed, approved answers.
- Facts written by code: prices, hours, doctors and order status come from approved records, and every number, time and link in a reply must trace back to a fact, a tool result or the conversation.
- Document answers carry proof: each claim is a sentence, a passage ID and a word-for-word quote, and code checks the exact match, the numbers, prices, negation and semantic closeness.
- Hybrid retrieval, full-text and pgvector fused with Reciprocal Rank Fusion, over versioned knowledge that moves from draft to approved to active and can roll back.
- A Postgres inbox for both channels: each message stored once, one turn per conversation under a lease, and each reply recorded before sending and sent at most once.
- A model gateway with routes approved per data class, a daily spend cap, a duplicate request when a call stalls and a fallback to a second model.
- Bookings through cal.com and Google Calendar. On WhatsApp the staff approve a booking request with a single tap.
- 4,155 tests at 97% branch coverage, property tests included, with import rules, offline evals and a container check in CI.
Key decisions
- Code owns the facts. A model that writes and is checked afterwards can still quote the wrong price, so the model leads the conversation and code supplies every number.
- A Postgres inbox instead of Temporal: Temporal Cloud would cost about $100 a month against about 0.014 EUR per message, and the channels need deadlines, not timers.
- Choices made by measurement, with the bar set in advance: a hosted embedder had to beat the local one by 10 points of recall@3, gained only 2.8, and the local model stayed.
- Live evals on demo businesses: 55 of 56 clinic cases and 23 of 23 shop cases passed, with no missed emergency and no invented fact getting through, at a p95 latency of 1.6 to 2.2 seconds.
- Code and client configuration are kept apart: one deployment per business, and all data in the repository is synthetic.
What's next
Next: deploying the WhatsApp and Instagram channels, then a limited FAQ release and a gradual rollout.
Source is private